Subsystem studies: scope and evidence
The twelve pages in this part answer one question each: for a given subsystem, what are the options and which one fits a 50 kg rover. A team dossier records what one team built and what happened. A subsystem study aggregates every team that could be documented and adds the component-level evidence that no single team publishes. Each study states the requirement, maps the design space, compares the options on benefits, drawbacks, relative cost and integration risk, and closes with a shortlist and the tests that remain open.
Key takeaways
- A dossier answers what a team built. A study answers which option fits, and that question cannot be answered from a sample of one.
- Every comparison row carries benefits, drawbacks, relative cost, complexity and integration risk, plus the evidence behind the row.
- Relative cost runs from
$to$$$$$inside one table only. A$$$antenna and a$$$gearbox are both average for their category, not the same price. - The evidence is uneven. Where nothing is published, the row says so, and the shortlist states what evidence would change the recommendation.
Why subsystem studies, after team dossiers
A team dossier answers what a team built and what happened. A subsystem study answers what the options are and which one fits. The second question cannot be answered by describing one team, because a single team is a sample of one. The twelve studies therefore aggregate every team that could be documented: 68 in the census, with the eight Tier A teams studied in depth, plus sister-competition and industry analogues where URC evidence is thin S-CENSUS. They then add component-level evidence that no single team publishes, from vendor datasheets to the soil mechanics that decide whether a wheel grips.
The structure is fixed, which is what makes the pages comparable. Twelve studies that each invented their own headings would be twelve essays. The same eight questions asked of every subsystem produce a set of tables that can be read against each other, and they are the reason the cross-subsystem analysis can be written at all.
| Part of a study | What it answers |
|---|---|
| Purpose and requirements | The subsystem’s job in each 2027 mission, traced to requirement identifiers |
| Design space | The architectures that exist, how they differ, and the variables that separate them |
| Comparison tables | Every option, with benefits, drawbacks, relative cost, integration risk and evidence |
| Cross-team patterns | What the top teams converge on, where they diverge, and what correlates with a score |
| Failure modes | The failures observed, their causes, and the design change that prevents a repeat |
| Interfaces | The inputs the subsystem needs and the outputs it owes the rest of the rover |
| Technical shortlist | The strongest option for each set of conditions, with no option removed for cost |
| Open problems | The tests that must settle each question, and the decision each one unblocks |
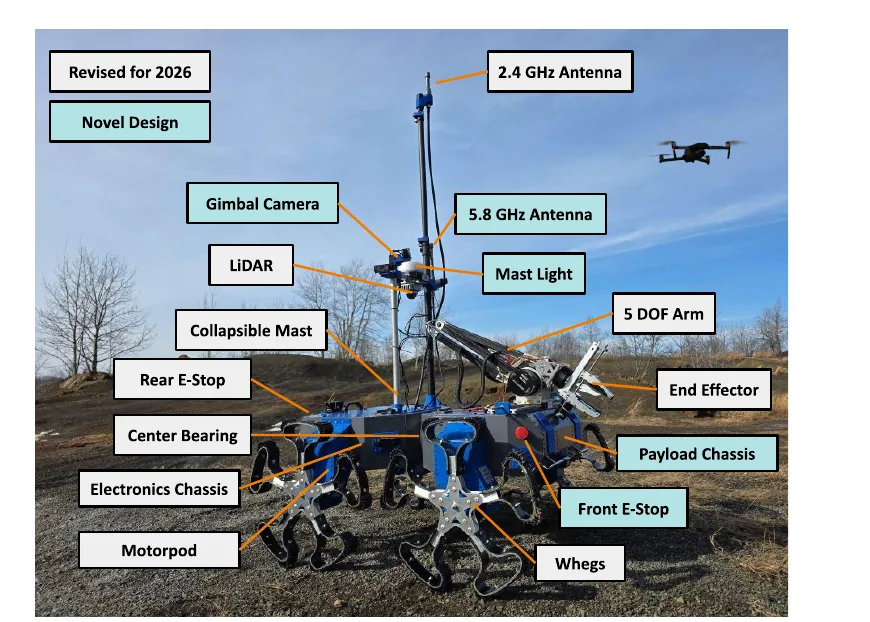
The twelve studies
The order is the reading order, and it runs from the subsystem every mission depends on to the one that exists only because the 2027 rules added it.
| Chapter | Study | Core question it answers |
|---|---|---|
| 4.1 | Mobility | How does the rover cross a kilometre of sand, rock and steep loose slope without getting stuck or tipping? |
| 4.2 | Arm and end-effectors | How does the arm reach from the ground to 1.5 m and work keys, locks, latches, hoses and a 5 kg cache? |
| 4.3 | Science and astrobiology payload | How does the rover find and prove, or exclude, life with two methods, one a bioassay, inside 30 minutes? |
| 4.4 | Delivery, payload handling and drones | How does the rover find, grasp, carry and deliver a 5 kg object over rough ground, and is a drone worth it? |
| 4.5 | Communications and networking | How does the rover keep a real-time video and control link at 1 km, out of line of sight, inside a metal trailer, on a shared band? |
| 4.6 | Power, electrical architecture and safety | How does the rover power a 40-minute mission with peaks, and guarantee that one button removes all battery power? |
| 4.7 | Compute, sensors and perception | What is needed to see ArUco tags at 1 cm, a walking astronaut, terrain and 5 kg objects? |
| 4.8 | Software stack and autonomy | How does the rover know where it is, plan a route, follow a person and recover safely when something goes wrong? |
| 4.9 | Operator station and operations | How do six people with no view of the rover run a 30–40 minute mission without mistakes? |
| 4.10 | Systems engineering and integration | How does a 50 kg rover fit inside a 1.2 m cube and pass the System Acceptance Review? |
| 4.11 | Environment, dust, thermal and repair | How does the rover survive the Mars Desert Research Station and the journey there, and how is it repaired in the field? |
| 4.12 | Astronaut interaction and the EVA suit | What does the 2027 astronaut-assistance sub-mission demand, and how are the suit and the interaction built? |
Delivery and drones is the exception. No comparable published account of the 2027 Delivery mission or its drones exists, so that page is a synthesis drawn from the rules, the Q&A, the team dossiers and the arm and astronaut studies. It says so in its opening paragraph, and its evidence is thinner than its siblings.
What a comparison row carries
The comparison table is the centre of each study, and it uses the same columns throughout. The column set is deliberately wider than a shopping list, because the option that wins on paper often loses on integration.
| Column | What it holds |
|---|---|
| Option and key specifications | What the thing is, with the numbers that separate it from the next row |
| Teams and years using it | Who built it, in which years, with the census tier beside the name |
| Benefits | The capability it buys, in physical terms rather than adjectives |
| Drawbacks and costs | What it costs in mass, volume, time, calibration or maintenance |
| Relative cost | $ to $$$$$ within this table only, or a list price with currency and date |
| Complexity and integration risk | What can go wrong in integration, how many subsystems it drags in, whether a first-year team can bring it up in one season |
| Evidence and links | A source identifier, and where useful a figure, a frame or a video timestamp |
Cost is one attribute among several
Relative cost is measured inside a single table and nowhere else. Nothing is removed from a comparison because it is expensive, and no row reasons about a team’s budget or funding. Where a list price was published it carries a currency and an access date; where it was not, the row says that a quote is required or that no price is published.
How strong the evidence is
URC teams publish unevenly, and a study that hid the difference would be less useful than one that shows it. Every row carries one of four grades.
| Grade | What it rests on |
|---|---|
| Strong | A team’s own report, repository or video, plus competition results, plus a manufacturer datasheet |
| Moderate | A video observation plus a team statement, or a single primary document |
| Weak | One photograph, one frame, or an analogue from another competition |
| Absent | Nothing published; the row records where it was looked for |
Two consequences follow. First, where the only evidence is a video frame, the study records what was seen and treats a part identification as an inference rather than a fact: an anodised can of about 40 mm with a planetary front cover is consistent with a Maxon GP42, which is not the same statement as knowing that it is one. Second, the shortlist states its confidence and what evidence would overturn it. A recommendation that cannot be tested is a preference.
Seventeen of the 68 census teams publish too little to support a dossier, and some subsystems are documented by only a handful of teams. The arm is the clearest case: only six of the roughly 36 teams that scored in 2026 publish enough to reconstruct an arm at all S-CENSUS.
Three reading paths
The twelve studies are not independent, and the most important decisions cut across them. Three paths are worth following in order.
- The mass-limited path. Power and energy mass, then mobility mass, then arm mass, then packaging in the 1.2 m cube, then mast and cable mass. This path establishes what 50 kg actually buys, and it ends at the cube rather than at a component.
- The task-limited path. Arm dexterity, then the science payload, then delivery, then astronaut interaction. This path establishes what the rover can do with its hands, and it is the one that decides whether the manipulator is a light chain of links or a 14 kg machine.
- The reliability path. Communications, then power and the E-stop, then perception and software failure handling, then operations, then environment and field repair. This path addresses why teams lose missions, and it is the path that converts a working rover into a scoring one.
Mass and power works the first path with numbers. Interfaces and couplings shows where the paths collide.
What the studies leave open
Three limits run across the whole part. The 2027 per-task weights are not published for Astrobiology, Delivery or Equipment Servicing, so every statement about the value of one task against another is a prediction S-URC27-RULES §1.b §1.c §1.d. Delivery has no dedicated study, for the reason given above. And most teams publish no rover mass or centre of gravity, which is why the mass figures in these pages carry ranges rather than single values.
The studies are also dated. Every claim carries the year it belongs to, because a 2024 design decision can be made wrong by a 2027 rule change: the two life-detection capabilities in the science payload, the key and lock transfer in the arm task set, and the removal of the marked-path task from Delivery are all changes that invalidate a design copied from an earlier year S-URC27-RULES §1.b.v §1.d.ii §1.c.iii.
Further reading
- The 2027 competition states the four missions and the scoring, which is the context every study assumes.
- 155 engineering requirements is the traced list the studies work from.
- The 68-team census gives the tiers and the results behind every “teams and years” column.
- Team dossiers hold the per-team detail the studies aggregate.
- Mission backfit turns the subsystem shortlists into a decision for each 2027 mission.
Sources for this page
- S-CENSUSURC team census, master index (68 teams, 187 team-year rows, tiers, documentation test)Print copy
- S-URC27-RULESUniversity Rover Challenge 2027 – Requirements and GuidelinesOriginal Archived copy